Sarvam AI
Sarvam Motif

Document AI

Turn complex files into clean data with Document AI

Parse, extract, classify and split complex documents in English and 22 Indian languages, all through a single API.

03Classify

Every document labelled and sent to the right place.

Your own document types, each with a confidence score.

  • Your own document types, no training
  • A confidence score on every label
  • Each type sent to its own fields

04Split

One PDF in, every document found.

Finds where each document starts and ends in one long PDF.

  • A page range for every document
  • Works on scans, photos and mixed files
  • Hands straight over to Classify

05Workflows

Chain the steps, then review only what needs it.

Coming soon

Chain every step on one canvas and run it as one API.

  • One canvas for the whole pipeline
  • Runs as a single API
  • People review only flagged values

Made for long,
messy, real files

01 · Extract

Just as accurate on the last page as the first

Extract reads every page of a long file, so values deep inside it come back as reliably as those on page 1.

See Extract

02 · Parse

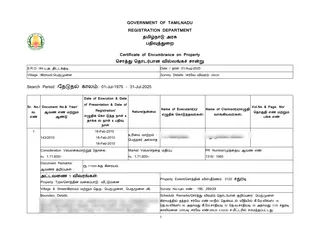
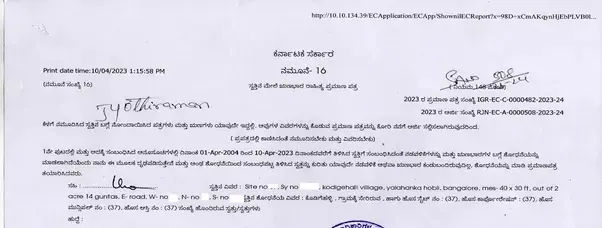
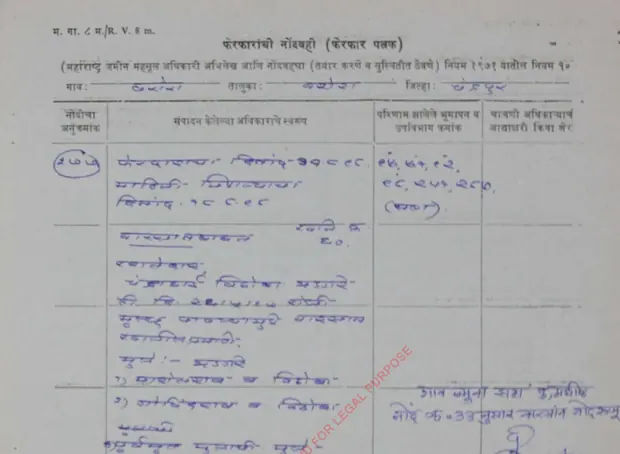
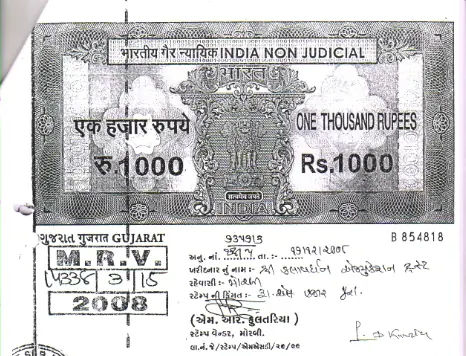
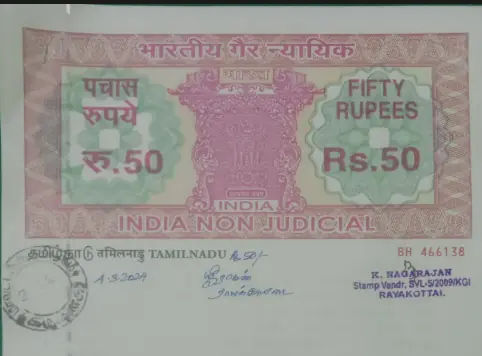
Indian scripts, handwriting and stamps

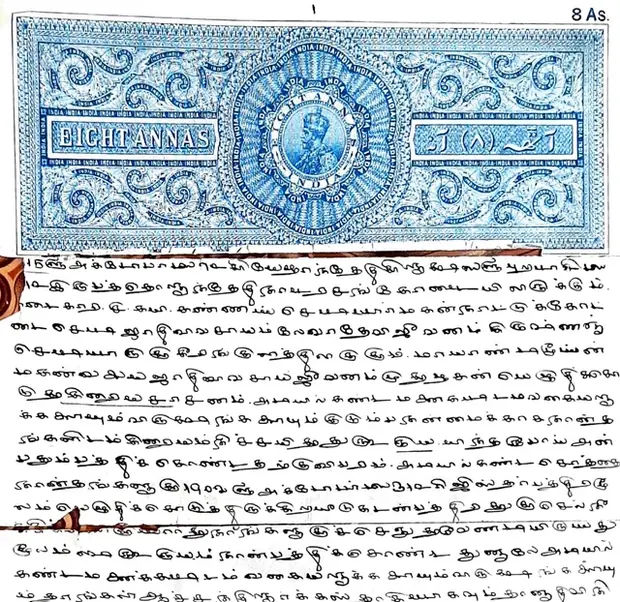
Parse reads print and handwriting in English and 22 Indian languages, including faded scans and stamped pages.

See Parse

03 · Parse

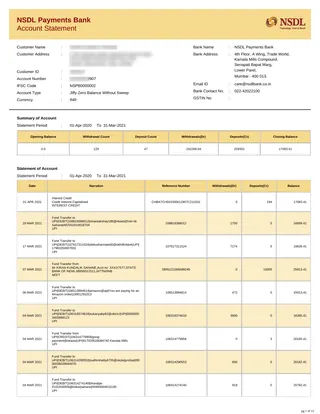
Complex tables, kept as tables

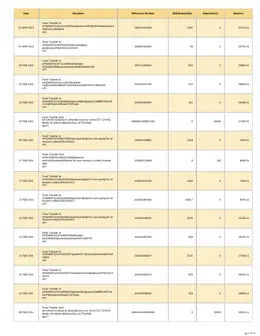
Parse keeps rows, columns and headers in place on dense, ruled tables like registers, ledgers and statements, and returns them as Markdown or HTML tables.

See Parse

04 · Extract

Empty when missing, never made up

If a value is not in the document, Extract returns it empty. Every value it does return comes with its page and a confidence score.

See Extract

Start with one API call

Every operation is a job. Submit the file, poll its status, then fetch the result.

curl -X POST https://api.sarvam.ai/doc-ai/v1/job/parse \  -H "api-subscription-key: $SARVAM_API_KEY" \  -F file=@./sample-document.pdf \  -F language="en-IN" \  -F output_format="md"# {"job_id": "<JOB_ID>", "status": "pending", ...}

Returns a job_id. Poll /job/{job_id}/status, then download the Markdown from /download-url.

Read the guide

Simple, per-page pricing

Prices are per page, before tax. Volume discounts apply as usage grows.

Parse

₹0.50 per page

Extract

₹1 per page

Classify

₹0.50 per page

Split

₹0.75 per page

Built for workflows that
run on documents

Start from the files your team already gets, and end with clean data your systems can use.

Lending and banking

Statements, applications and property papers arrive in one bundle. Every value the underwriter needs comes back with its page.

  • Bank statements
  • Loan applications
  • Land records
  • KYC

Insurance

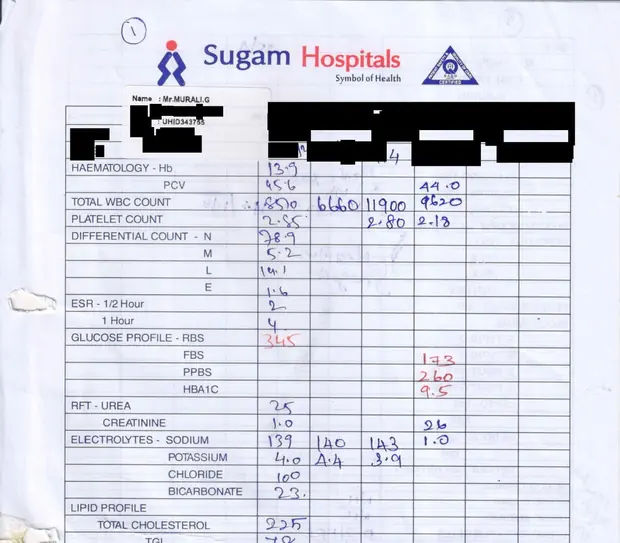
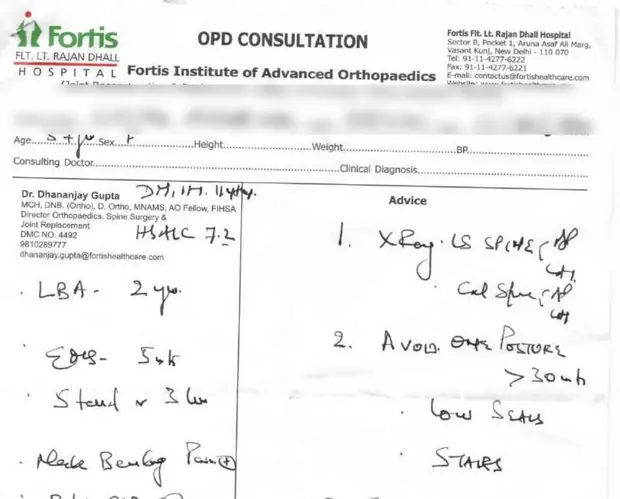
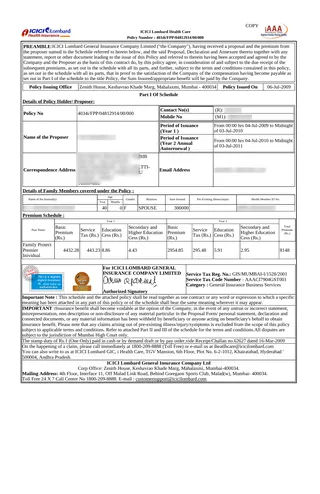
Policy schedules, claim forms and hospital records are read before anyone opens them. Anything uncertain goes to a person.

  • Policy schedules
  • Claim forms
  • Lab reports
  • Prescriptions

Utilities and payables

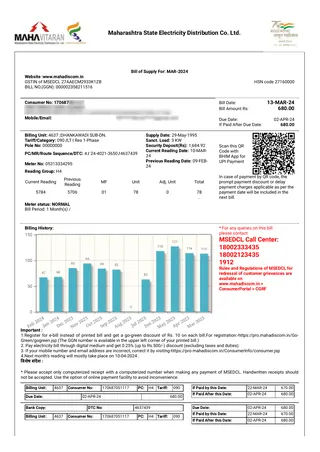
Bills, invoices and purchase orders all come out in the same format, so reconciliation starts from clean data instead of paper.

  • Utility bills
  • GST invoices
  • Purchase orders
  • Receipts

Government and land records

Encumbrance certificates, registers and land ledgers come back as clean data, with values kept in their original script.

  • Encumbrance certificates
  • Land records
  • Registers
  • Circulars

Legal and contracts

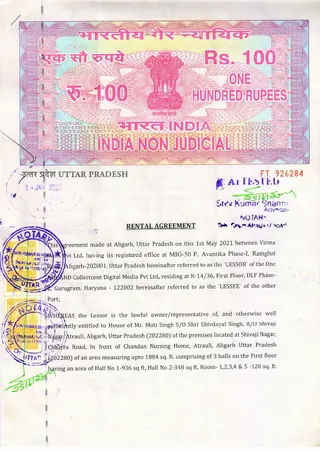
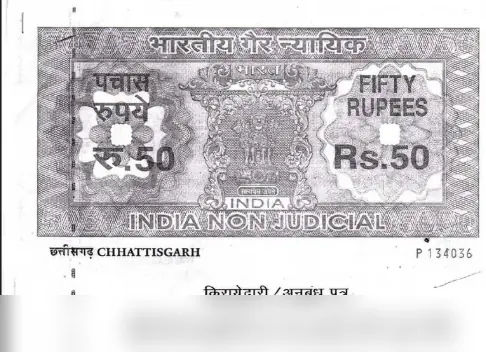
Agreements on stamp paper, even skewed or photocopied ones, come back with their parties, dates and stamp details.

  • Stamp-paper agreements
  • Rent and lease deeds
  • Sale deeds
  • Powers of attorney

Handwritten forms

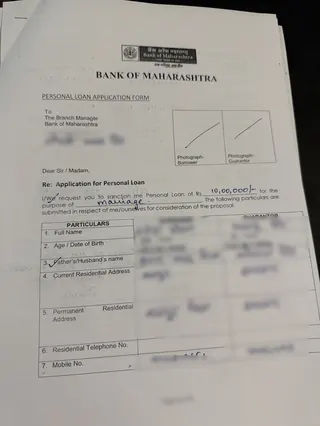
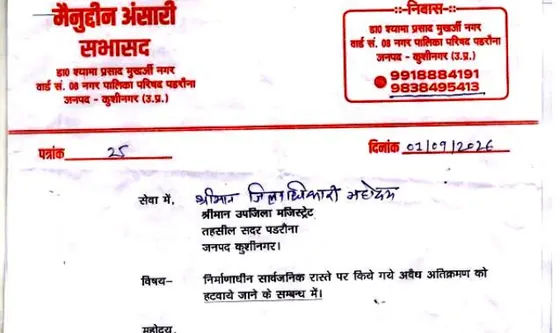
Forms filled in by hand, in Hindi or English, come back as clean fields. A blank field stays blank instead of being guessed.

  • Loan forms
  • Account opening
  • Field surveys
  • Grievance letters

Knowledge bases and search

Not every team needs fields. Policies, circulars and case files are parsed whole, with headings and tables intact, so your search and AI assistants work from the full document.

  • Policy documents
  • Circulars
  • Manuals
  • Case files

Deploy where your data lives

The same models and workflows, in the environment you choose.

Sarvam Cloud

Fully managed in India, and the fastest way to start

On-premises

Runs in your own data centre, so documents never leave it

Private cloud (VPC)

Runs inside your cloud account, under your network controls

Enterprise-ready. Built for privacy

Security & privacy

Enterprise-grade security

Process loan files, claims and contracts on ISO 27001:2022 certified, SOC 2 Type II attested infrastructure.

  • Information security ISO 27001:2022 Certified
  • Controls attestation SOC 2 Type II Certified

Built for privacy

Your documents remain yours. We do not train on them, and you decide how long they are retained.

Your documents Never used for training Private
Retention
Set by you
Processing
In India, or on your servers
Every value
Traceable to its page

Your questions, answered

Bring your most complex document. See it structured in minutes.